Performance

The larger the data, the longer it takes to prepare and present information. BI, ETL and newer data blending tools cannot integrate or deliver data sets that exceed storage and require large servers with appliances, in-memory databases or even Hadoop.
What if, at reporting time, you could leverage a proven big data preparation engine that uses multi-threading and scales linearly across your file system? In other words, if you could connect data integration with faster and more reliable insights and AI models.
Complexity

When IT integrates data for business users, reporting results can be compromised. DW ETL activities and data services can reflect incorrect or duplicate data sources, values, formats and types. The disconnect comes from their different missions, methodologies and platforms.
What if business and IT users could easily identify, validate, cleanse and normalize (homogenize/standardize) all the data sources that feed the reports or populate the data lake?
Quality
Trying to manage the variety of data formats from different silos and feeds often requires multiple tools and even specialized techniques from multiple people. Time to adoption and time to value lags behind the adoption and use of different platforms controlled by IT.
Security
Encryption, pseudonymization and other data masking functions that are required to comply with data protection regulations usually require other software products and/or processing steps.
What if field-level security functions could be applied directly at report or data preparation time?
Costs
Large data preparation tools (ETL) and hardware technologies (Hadoop) as well as the most sophisticated BI and data blending platforms are expensive to purchase, implement, configure and maintain.
What if you just needed a product supported in a free Eclipse GUI that provides everything you need to report directly with integrated tools or quickly prepare data for your own?
Redundancy
Not only is integrated data in the BI layer slow (or impossible) given the volume, variety, velocity and veracity of today's data, but its internal data integration processes are inherently complex, require repetition and create data synchronization issues.
Centralized data preparation, on the other hand, solves these problems, allows changes to source data to be managed in one place, and creates better data targets that are suitable for multiple reports.
Integrate BI
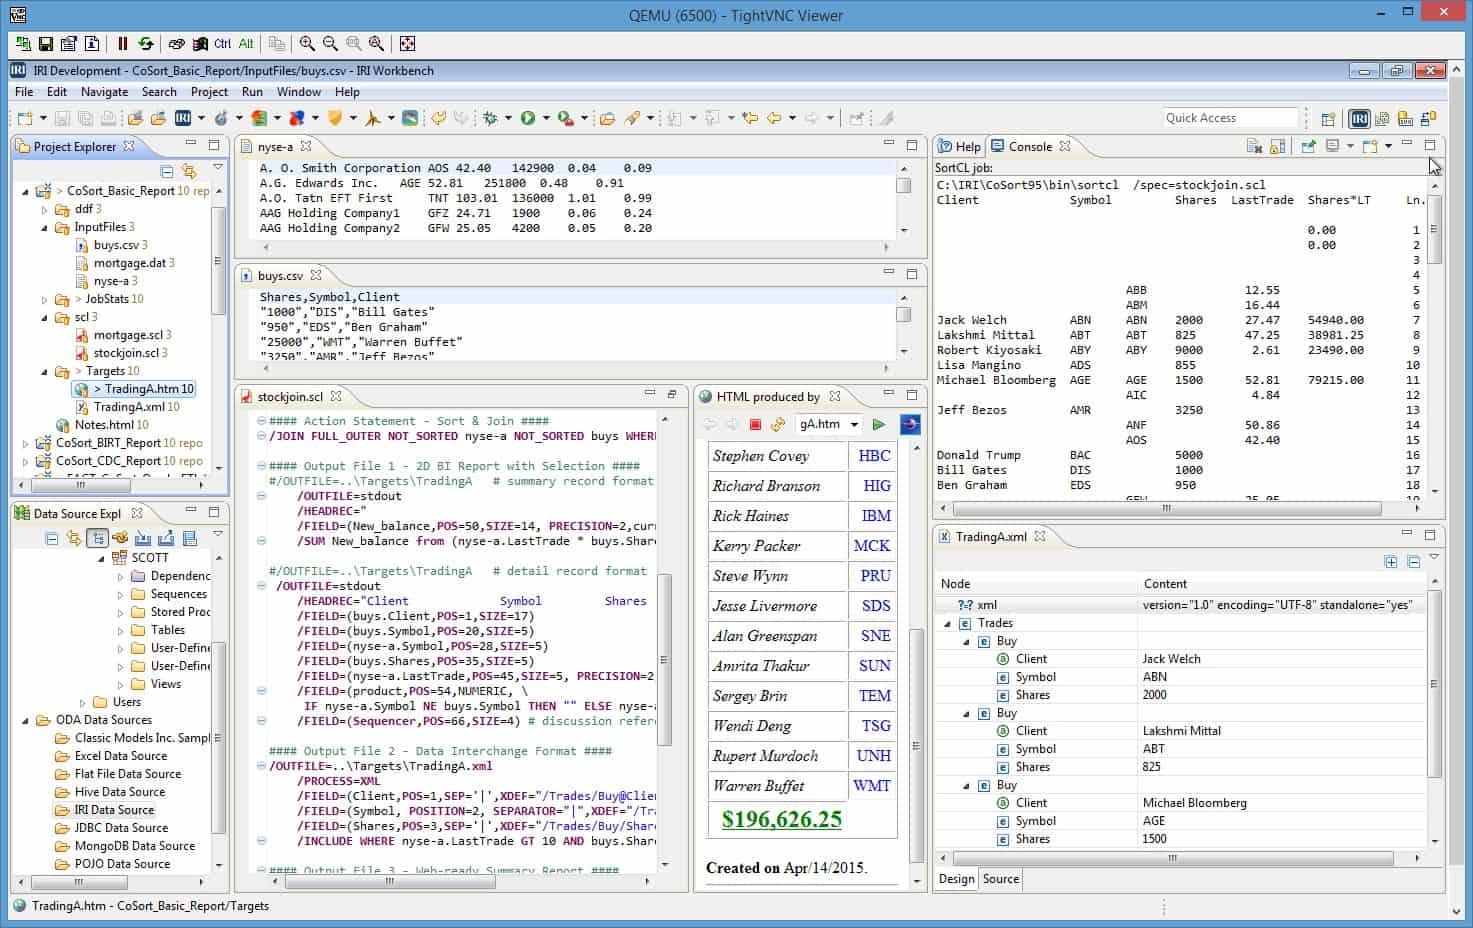
IRI's integrated reporting capabilities allow you to optimize BI results when transforming large amounts of data. Integrated formatting capabilities allow you to capture the value of information seamlessly and in the shortest possible time.
KNIME AI Integration
Splunk integrations
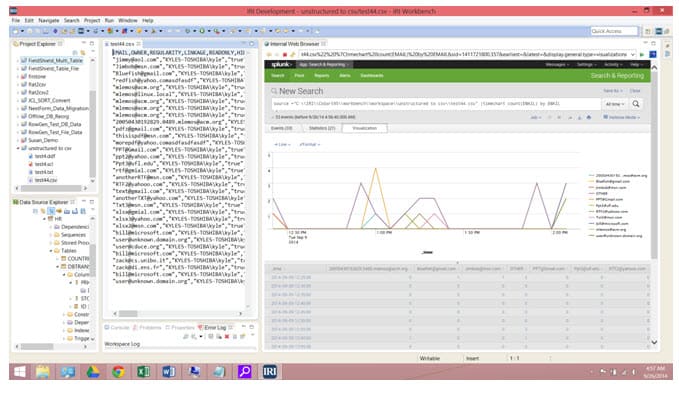
Put Splunk into overdrive. IRI's free Splunk add-on for Voracity simultaneously indexes large or dark data from Voracity. Cleans, transforms and masks your data as you enter it into Splunk!.
Cloud dashboard
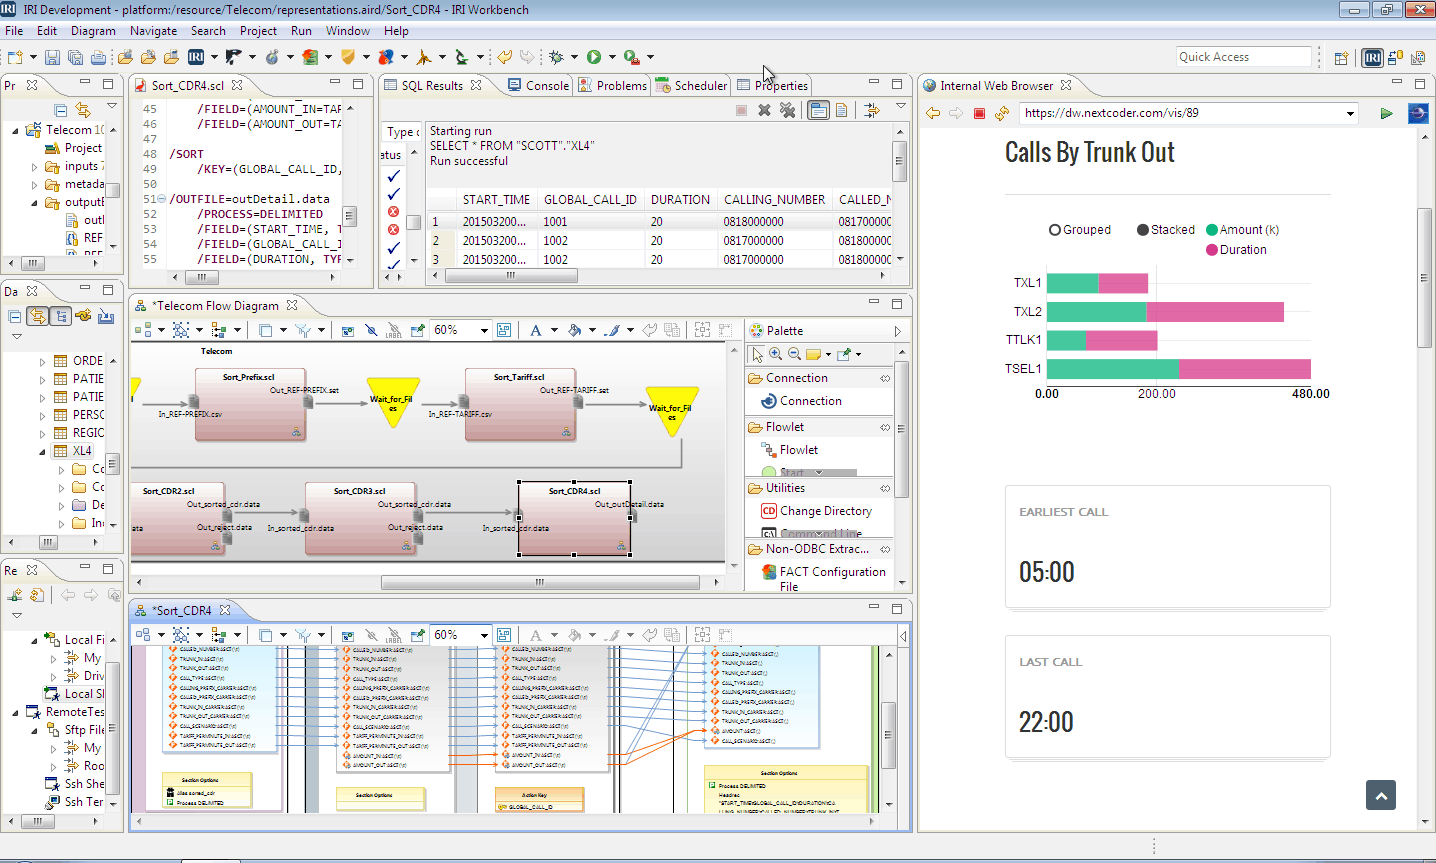
See and learn more with a modern dashboard in the IRI Workbench GUI or in your browser. Visualize and interact with data that you can transform, cleanse and mask in Voracity. Prepare anywhere and see information everywhere.